
On this article, you’ll learn to design AI brokers that may reliably self-correct by grounding their suggestions loops in exterior verification somewhat than the mannequin’s personal judgment.
Subjects we’ll cowl embody:
- Why self-correction in language fashions solely works when the agent has an exterior sign to examine in opposition to, and when it isn’t value the associated fee.
- The best way to construct a code-generation agent with an actual test-based verifier, a bounded retry loop, and a structured escalation path.
- The best way to add a consistency-based confidence gate that generates an unbiased second answer to verify correctness earlier than transport.
Introduction
In 2024, a crew of researchers revealed a paper with a blunt title: “Large Language Models Cannot Self-Correct Reasoning Yet.” Their discovering was uncomfortable for anybody constructing brokers on the time. Whenever you ask a mannequin to examine its personal reasoning with no exterior enter, it doesn’t reliably catch its errors. Generally it does the other: it talks itself into believing a improper reply is correct, and the “corrected” model comes out worse than the primary draft, a sample later work has confirmed and constructed on.
That discovering sits on the middle of every part on this article. Self-correction in AI brokers is actual; it isn’t a trick or a advertising and marketing time period, but it surely solely works underneath a particular situation: the agent wants one thing exterior its personal opinion to examine in opposition to. Give it that, and the loop catches actual errors. Skip it, and also you’ve constructed an elaborate approach for the mannequin to agree with itself.
This tutorial builds one full instance in order that the situation stays concrete somewhat than summary: a code-generation agent that writes a Python perform, truly runs the perform’s exams, fixes what fails, and is aware of when to cease attempting and hand the issue to an individual as a substitute.
Conditions:
- Python 3.10 or newer
- An Anthropic API key
-
pip set up langgraph langchain–anthropic pytest python–dotenv
Why Asking a Mannequin to Test Its Personal Work Normally Fails
Image asking a scholar to grade their very own examination with no reply key. They’ll repair the errors they discover, however the errors they don’t discover are precisely those they’ll approve once more on a re-assessment. That’s the coherence lure: a language mannequin’s critique of its personal output is generated by the identical weights, skilled on the identical patterns, that produced the output within the first place. It’s not an unbiased examine. It’s the identical judgment requested twice, and the 2 solutions are likely to agree, whether or not or not both is appropriate.
This doesn’t imply reflection is nugatory; it means reflection solely works when it’s grounded in one thing the generator didn’t produce. The unique Reflexion paper out of Stanford confirmed brokers with verbal self-reflection reaching 91% go@1 on HumanEval, up from an 80% baseline, and a 20-point absolute achieve on HotpotQA query answering over an ordinary ReAct agent. Madaan et al.’s Self-Refine paper discovered an analogous 20% common enchancment throughout seven totally different duties. These are actual features, and what they’ve in widespread is that the duties gave the mannequin one thing to examine in opposition to: code has exams that both go or fail, and multi-step retrieval has paperwork that both reply the query or don’t.
The place reflection stops paying its approach is less complicated duties with nothing exterior to examine. The 2025 CorrectBench study discovered self-correction provides roughly 5% on laborious reasoning benchmarks like MATH, however on simple duties, plain chain-of-thought reasoning does simply as nicely utilizing 40% much less compute. Reflection isn’t free. It prices tokens, latency, and cash each time the loop runs, so the query value asking earlier than you construct one isn’t “would reflection assist,” it’s “do I’ve one thing exterior for the critic to examine in opposition to, and is the duty laborious sufficient to justify the additional calls?”
That’s the rule the remainder of this text follows: floor the critic in one thing the generator didn’t write. For code, that’s operating the exams. For analysis, that’s a retrieved supply. For a form-filling agent, that’s schema validation. No matter your venture is, discover that exterior sign earlier than you write a single line of correction logic, as a result of with out it, you’re constructing a dearer model of the identical mistake.
The Constructing Blocks, Earlier than You Write Any Code
5 items present up in nearly each manufacturing self-correction system, and it’s value figuring out what each is definitely for earlier than wiring them collectively.
- Reflection loops are the generate-critique-revise cycle itself. The loop solely works if it’s bounded. An unbounded reflection loop isn’t a security function; it’s a legal responsibility, and a broadly shared 2026 postmortem described a document-processing agent that entered a retry loop in a single day and ran up a $437 bill in eight hours earlier than anybody seen. Each loop on this article carries a tough cap.
- Verifiers examine the generator’s output. The necessary distinction is between a verifier and a calibration mannequin: a verifier scores output high quality in a approach that’s unbiased of which mannequin produced it, whereas a calibration mannequin estimates how assured the particular producing mannequin ought to be in its personal output, which is a subtly totally different and weaker sign, as a 2025 paper on fine-grained confidence estimation lays out. In manufacturing, the strongest and most cost-effective verifiers are normally the only: run the code, examine the schema, question the database. Save skilled course of reward fashions, which rating intermediate reasoning steps somewhat than solely the ultimate reply, for instances the place you genuinely can’t execute or examine the output immediately.
- Confidence scoring sounds prefer it ought to resolve the “how positive is the agent” query cheaply, however present analysis is direct about its limits. A 2026 ACL paper on uncertainty quantification examined three widespread approaches (log-probability, self-consistency sampling, and verbalized confidence) on agent duties and located all three scored near a random guess for predicting failure, with AUROC values round 0.55 to 0.6 in opposition to a 0.5 baseline. Verbalized confidence, the most affordable choice because it simply means asking the mannequin how positive it’s, can also be the least dependable as soon as an agent’s context will get lengthy and noisy. The extra reliable model of confidence scoring in apply is consistency-based: generate an answer twice, independently, and examine whether or not they agree. Disagreement is an actual sign. Two unbiased makes an attempt agreeing with one another are meaningfully stronger proof than one try saying “I’m 95% positive.”
- Retry insurance policies govern what occurs after a failure. The usual sample is exponential backoff with jitter — wait a bit longer after every failure with some randomness added so a fleet of brokers doesn’t all retry on the identical second — paired with a circuit breaker so a sustained outage journeys the entire name web site as a substitute of hammering a struggling service for an hour. The element that catches groups off guard is that this must be enforced exterior the mannequin’s personal reasoning. An agent that decides by itself to “attempt a distinct strategy” after a timeout continues to be retrying, simply invisibly, and infrastructure-level charge limits can’t see a retry that’s occurring contained in the mannequin’s chain of thought somewhat than as a definite API name.
- Restoration structure is what occurs as soon as the retry price range is spent. A circuit breaker and a kill swap resolve totally different issues: a kill swap is an individual noticing one thing improper and stopping it manually, whereas a circuit breaker is an automated rule that journeys earlier than an individual wants to note something. The top state of a superb restoration path will not be “crash,” it’s a clear escalation with the total failure trajectory logged someplace an individual can truly learn it, which is similar thought behind dead-letter queues in conventional fault-tolerant methods, utilized to agent failures as a substitute of message queues.
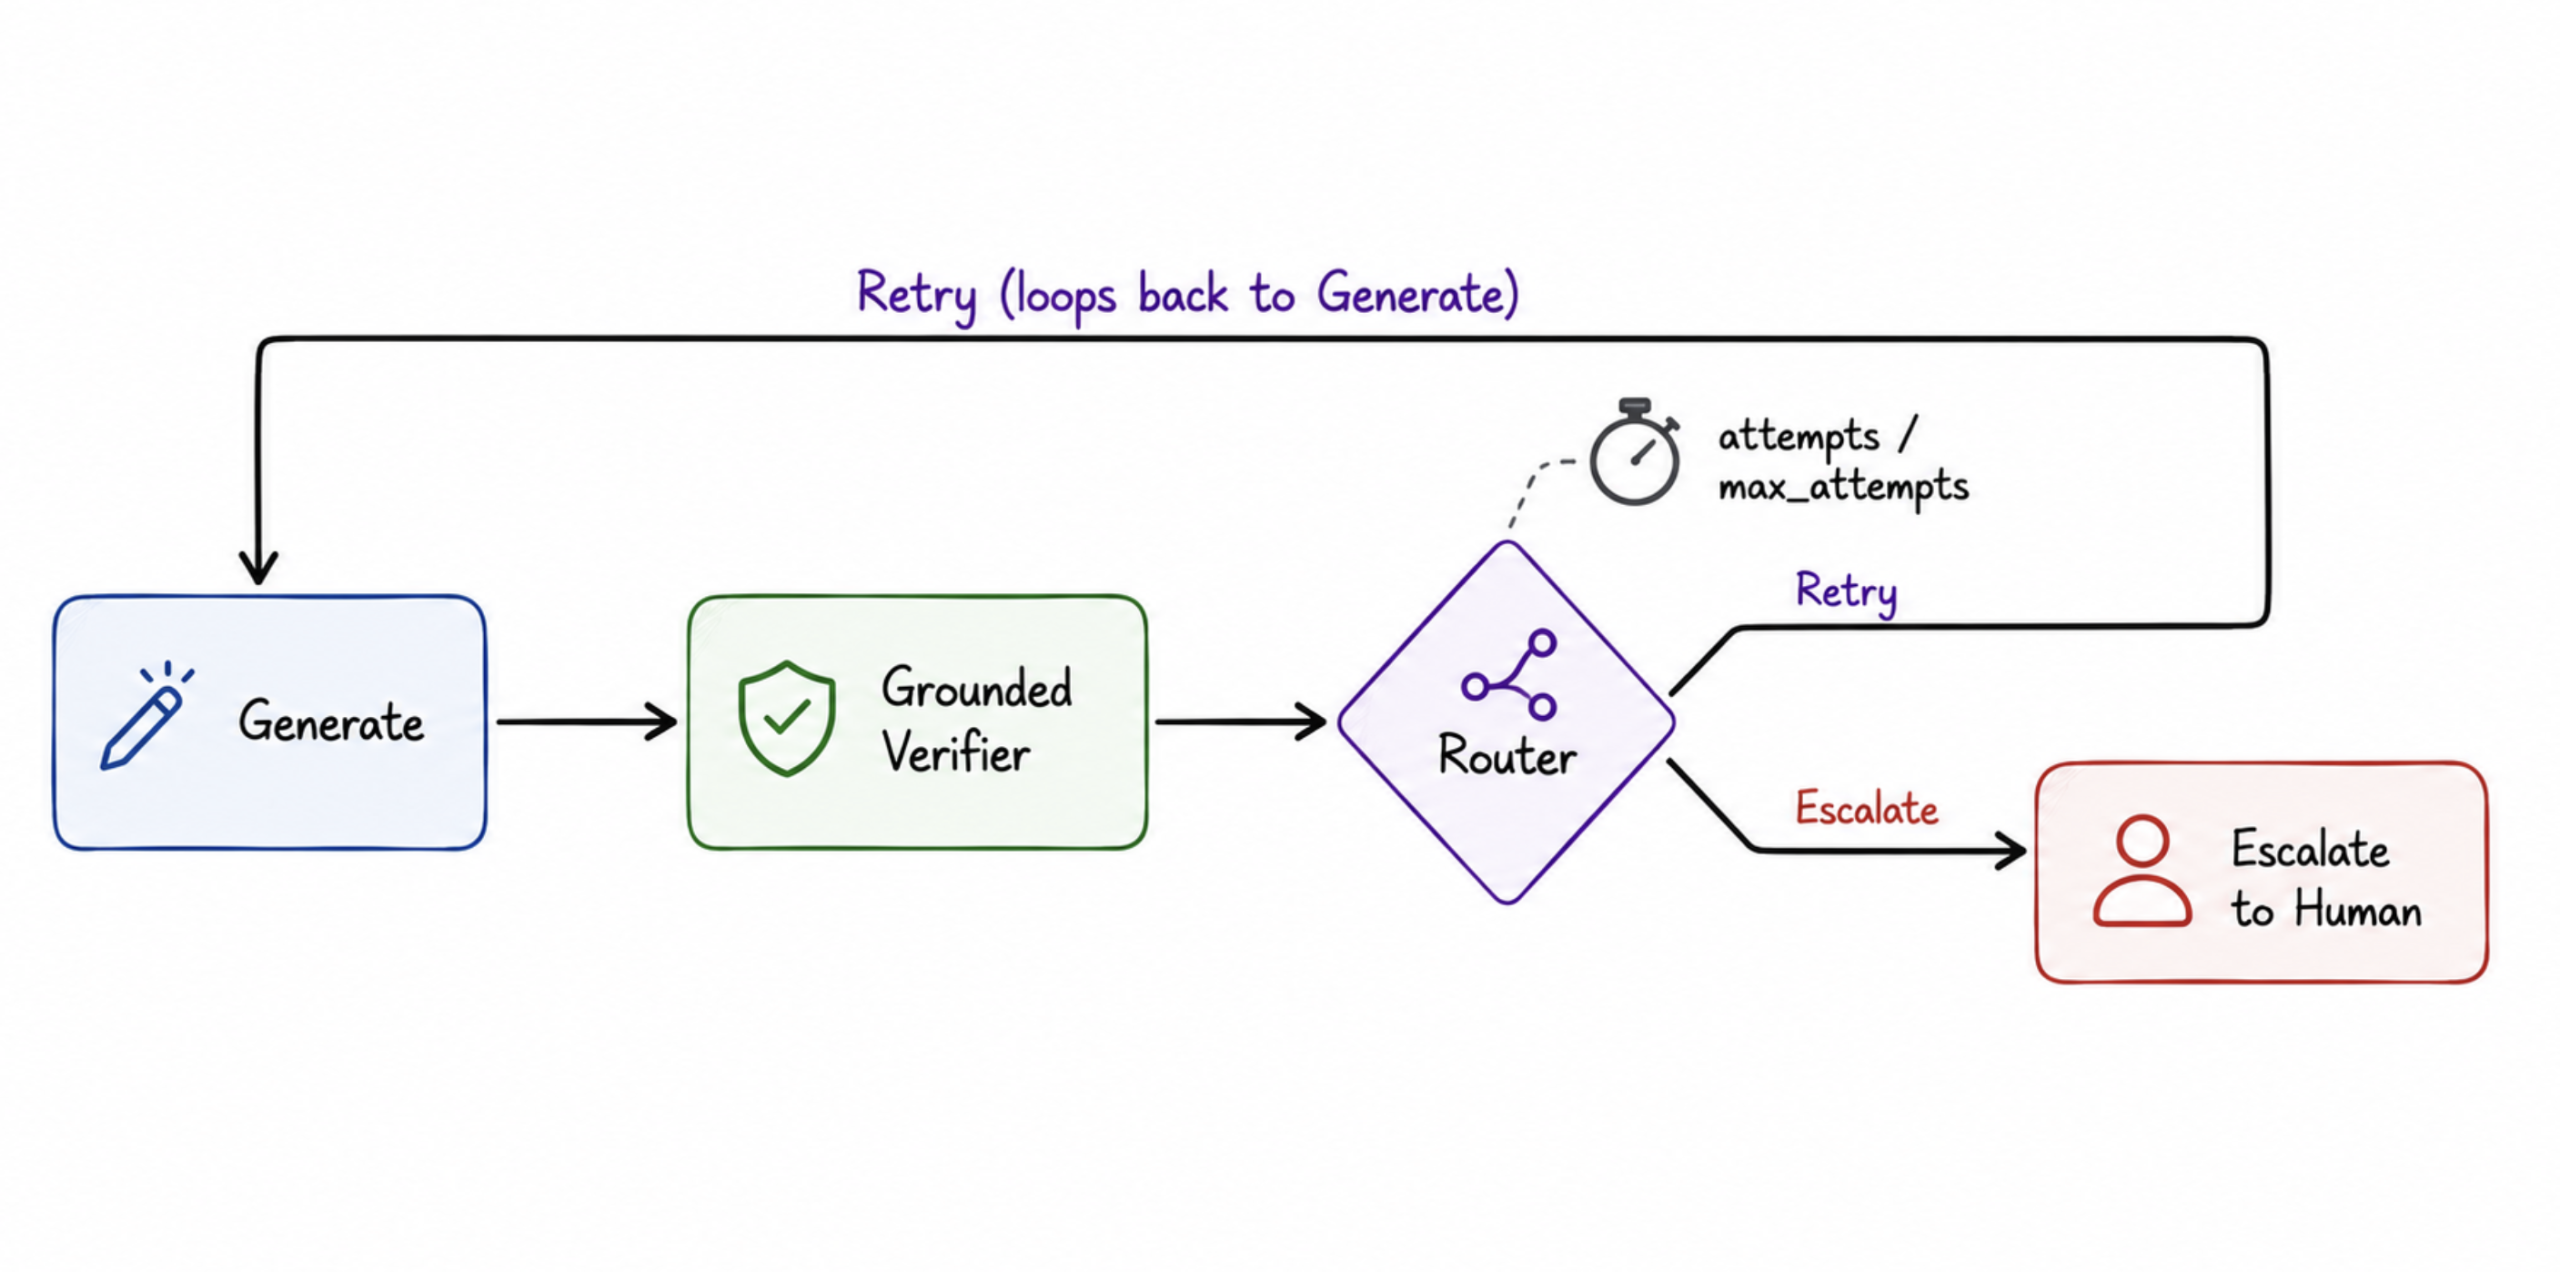
A horizontal movement diagram: Generate, Grounded Verifier, Router and Retry (click to enlarge)
With the vocabulary and the failure modes in place, right here’s the construct.
Construct the Generator and the Grounded Verifier
The venture: an agent that receives a brief perform spec, writes the implementation, and checks it in opposition to an actual check file somewhat than its personal judgment of whether or not the code seems appropriate.
Begin with the venture folder:
|
mkdir self–correcting–agent && cd self–correcting–agent python3 –m venv venv supply venv/bin/activate pip set up langgraph langchain–anthropic pytest python–dotenv |
Create a .env file along with your key:
|
# .env ANTHROPIC_API_KEY=your–anthropic–key–right here |
Now the generator, which asks Claude to jot down a perform primarily based on a spec, and consists of the earlier failure as suggestions if this isn’t the primary try:
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 |
# agent.py import os from dotenv import load_dotenv from langchain_anthropic import ChatAnthropic
load_dotenv()
mannequin = ChatAnthropic(mannequin=“claude-sonnet-4-6”, temperature=0.2, max_tokens=500)
def generate_code(spec: str, suggestions: str | None) -> str: “”“Asks the mannequin to jot down a perform matching the spec. If suggestions from a failed check run is supplied, it is included so the mannequin is not guessing blind on retries.”“” immediate = f“Write a single Python perform for this spec:n{spec}n” immediate += “Return solely the perform code, no clarification, no markdown fences.” if suggestions: immediate += f“nnThe earlier try failed these exams:n{suggestions}nFix it.”
response = mannequin.invoke(immediate) # Strip markdown fences in case the mannequin provides them regardless of directions code = response.content material.strip() if code.startswith(““`”): code = code.cut up(““`”)[1] if code.startswith(“python”): code = code[len(“python”):] return code.strip() |
What this does: the perform builds a single immediate that features the spec and, critically, the precise check failure output from the final try when there’s been one. That suggestions is what separates this from a blind retry; the mannequin isn’t producing a contemporary guess every time, it’s responding to particular proof of what broke. The markdown-stripping on the finish handles a typical annoyance: fashions usually wrap code in fences even when instructed to not, and leaving these in would break the file we’re about to jot down to disk.
Subsequent, the verifier — the half doing the precise grounding:
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 |
# verifier.py import subprocess import tempfile from pathlib import Path
def run_tests(code: str, test_code: str) -> tuple[bool, str]: “”“Writes the generated code and a check file to a short lived listing and really runs pytest in opposition to them. That is the exterior examine the generator cannot discuss its approach round — the exams both go or they do not.”“” with tempfile.TemporaryDirectory() as tmp: tmp_path = Path(tmp) (tmp_path / “answer.py”).write_text(code) (tmp_path / “test_solution.py”).write_text(test_code)
consequence = subprocess.run( [“python3”, “-m”, “pytest”, “test_solution.py”, “-q”], cwd=tmp_path, capture_output=True, textual content=True, timeout=15, ) handed = consequence.returncode == 0 output = consequence.stdout + consequence.stderr return handed, output |
What this does: this perform has no opinion of its personal about whether or not the code is nice. It writes the mannequin’s output to an actual file, runs pytest in opposition to it as a real subprocess, and stories again precisely what pytest stories: go, fail, and the particular assertion errors if it failed. There’s no LLM name wherever on this perform. That absence is the whole level. That is the grounded sign that the primary part argued you want earlier than reflection is value constructing in any respect.
Add the Correction Loop with a Bounded Retry Finances
With a generator and an actual verifier, the subsequent step is wiring them right into a loop that retries on failure, feeds the check output again as suggestions, and stops after a hard and fast variety of makes an attempt. That is the place LangGraph earns its place: the state machine mannequin makes the cycle, and its exit situations, specific as a substitute of buried in nested if-statements.
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 54 |
# graph.py from typing import TypedDict, Non-compulsory from langgraph.graph import StateGraph, END from agent import generate_code from verifier import run_tests
class AgentState(TypedDict): spec: str test_code: str code: str suggestions: Non-compulsory[str] makes an attempt: int max_attempts: int standing: str
def generate_node(state: AgentState) -> AgentState: code = generate_code(state[“spec”], state.get(“suggestions”)) return {**state, “code”: code}
def verify_node(state: AgentState) -> AgentState: handed, output = run_tests(state[“code”], state[“test_code”]) makes an attempt = state[“attempts”] + 1 if handed: return {**state, “makes an attempt”: makes an attempt, “standing”: “verified”, “suggestions”: None} return {**state, “makes an attempt”: makes an attempt, “standing”: “failed”, “suggestions”: output[–800:]}
def escalate_node(state: AgentState) -> AgentState: # In manufacturing that is the place you’d log the total trajectory to a # database or ticket queue as a substitute of simply altering the standing return {**state, “standing”: “escalated”}
def router(state: AgentState) -> str: “”“That is the correction price range in code. Failure alone does not loop endlessly — it loops till makes an attempt hits the cap, then stops for good.”“” if state[“status”] == “verified”: return “finish” if state[“status”] == “failed” and state[“attempts”] state[“max_attempts”]: return “retry” return “escalate”
builder = StateGraph(AgentState) builder.add_node(“generate”, generate_node) builder.add_node(“confirm”, verify_node) builder.add_node(“escalate”, escalate_node) builder.set_entry_point(“generate”) builder.add_edge(“generate”, “confirm”) builder.add_conditional_edges(“confirm”, router, { “retry”: “generate”, “escalate”: “escalate”, “finish”: END, }) builder.add_edge(“escalate”, END)
graph = builder.compile() |
What this does: AgentState is the shared reminiscence the entire loop reads and writes, monitoring not simply the code however the try depend and standing, which is what makes the cap enforceable. verify_node is the place the true check output turns into suggestions for the subsequent technology try, if there’s one. The router perform is the only most necessary piece of this file: it’s a plain Python perform, not a immediate, deciding whether or not to loop, cease, or hand off, which implies the retry cap can by no means be argued out of by the mannequin’s personal reasoning, the best way an infrastructure-level timeout might be. That distinction is strictly what the circuit breaker analysis cited earlier factors to as the true repair — not an even bigger kill swap, however a rule that lives exterior the agent’s personal decision-making.
To run it, add a small entry level:
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 |
# run.py from graph import graph
spec = “write is_palindrome(s), a perform that returns True if a “ “string reads the identical forwards and backwards, ignoring case and areas”
test_code = “”“ from answer import is_palindrome
def test_simple_true(): assert is_palindrome(“stage“) is True
def test_simple_false(): assert is_palindrome(“hi there“) is False
def test_ignores_case_and_spaces(): assert is_palindrome(“Nurses Run“) is True ““”
consequence = graph.invoke({ “spec”: spec, “test_code”: test_code, “code”: “”, “suggestions”: None, “makes an attempt”: 0, “max_attempts”: 3, “standing”: “pending”, })
print(“Standing:”, consequence[“status”]) print(“Makes an attempt used:”, consequence[“attempts”]) print(“nFinal code:n”, consequence[“code”]) |
The best way to run it: along with your .env file in place and the digital setting energetic, run python run.py. On a spec like this, don’t be stunned if the primary try fails; a first-pass implementation generally ignores case or areas, precisely just like the naive s == s[::-1] model does, and it’s genuinely helpful to look at the loop catch that, feed the pytest failure again in, and produce a corrected model on the second go.
Add a Confidence Gate Earlier than Something Ships
Passing the exams you wrote isn’t the identical as being appropriate. An answer can go three check instances and nonetheless be fragile on inputs no person thought to examine. For the reason that second part coated why self-reported confidence scores are solely barely higher than guessing, the gate we’re including right here makes use of the extra dependable sign as a substitute: generate a second, unbiased answer to the identical spec, and examine whether or not it agrees with the primary one on instances past the unique exams.
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 |
# confidence_gate.py from agent import generate_code from verifier import run_tests
EDGE_CASES = “”“ from answer import is_palindrome
def test_empty_string(): assert is_palindrome(““) is True
def test_single_character(): assert is_palindrome(“a“) is True
def test_mixed_case_and_punctuation_spacing(): assert is_palindrome(“A Santa At NASA“) is True ““”
def confidence_check(spec: str, primary_code: str, main_test_code: str) -> dict: “”“Generates an unbiased second answer and checks whether or not each options agree on the unique exams plus a held-out set of edge instances the correction loop by no means noticed. Settlement between two unbiased makes an attempt is a stronger sign than both mannequin asking itself how assured it feels.”“” second_code = generate_code(spec, suggestions=None)
second_on_main, _ = run_tests(second_code, main_test_code) primary_on_edges, _ = run_tests(primary_code, EDGE_CASES) second_on_edges, _ = run_tests(second_code, EDGE_CASES)
agree = second_on_main and primary_on_edges and second_on_edges return { “confirmed”: agree, “second_code”: second_code, “primary_passed_edges”: primary_on_edges, “second_passed_edges”: second_on_edges, } |
What this does: the held-out edge instances (empty strings, single characters, punctuation) had been by no means proven to the correction loop, so passing them isn’t one thing both answer may have been particularly patched for. The second answer additionally has to clear the unique check file by itself, written independently, with no reminiscence of the primary try’s errors.
If an independently generated second try and the unique each clear all of that, the settlement itself is the boldness sign — not a quantity the mannequin stories about its personal certainty. When this sample is examined, the second differently-written answer and the corrected first one sometimes agree on each case, which is the result that allows you to ship with no human within the loop. Once they disagree, that’s not a minor discrepancy to shrug off; it’s precisely the form of sign that ought to path to an individual, because it means the exams you wrote weren’t strict sufficient to completely pin down the right conduct within the first place.
Wire this into the graph as yet one more node after verification passes, routing to escalation on disagreement as a substitute of a silent go:
|
# in graph.py, add: from confidence_gate import confidence_check
def confidence_node(state: AgentState) -> AgentState: consequence = confidence_check(state[“spec”], state[“code”], state[“test_code”]) if consequence[“confirmed”]: return {**state, “standing”: “confirmed”} return {**state, “standing”: “escalate_disagreement”} |
Replace the router so “verified” results in “confidence_node” as a substitute of straight to END, and add a conditional edge out of it that sends “confirmed” to END and the rest to “escalate”. The form of the graph stays the identical — generate, confirm, gate, escalate — it simply will get yet one more grounded examine earlier than calling something achieved.
What Occurs When the Agent Can’t Repair Itself
A retry price range solely works if hitting it truly does one thing helpful as a substitute of simply quietly failing. The escalate_node within the graph above is intentionally bare-bones as written; in an actual deployment, it must do three issues: cease the loop for good (which the router already ensures), report precisely what was tried, and put the failure someplace an individual will truly see it.
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 |
# restoration.py import json from datetime import datetime, timezone
def log_escalation(state: dict, log_path: str = “escalations.jsonl”) -> None: “”“Appends the total failure trajectory to a log file. In manufacturing, swap this for a write to a database or a ticket in your crew’s queue — the purpose is that nothing will get silently dropped.”“” report = { “timestamp”: datetime.now(timezone.utc).isoformat(), “spec”: state[“spec”], “final_code”: state[“code”], “makes an attempt”: state[“attempts”], “last_feedback”: state.get(“suggestions”), “standing”: state[“status”], } with open(log_path, “a”) as f: f.write(json.dumps(report) + “n”) |
What this does: this is similar thought behind a dead-letter queue in odd distributed methods, utilized to an agent’s failure as a substitute of a message that couldn’t be processed. Nothing right here tries to repair the issue once more. It information precisely what spec was given, what the final try appeared like, and why it failed, so an individual selecting this up later isn’t ranging from zero. Name log_escalation(consequence) proper after graph.invoke(…) each time consequence[“status”] isn’t “confirmed”, and you’ve got a clear, auditable path as a substitute of a print assertion that scrolled off a terminal three deploys in the past.
That is additionally the purpose value remembering from the very first part. The circuit breaker right here isn’t a comfort prize for a system that didn’t be totally autonomous. It’s the factor that makes the autonomy reliable within the first place, as a result of a system that is aware of precisely when to cease and ask for assistance is a extra dependable system than one which at all times claims to have the reply.
Wrapping Up
All the pieces on this construct comes again to 1 thought: a self-correcting agent is simply pretty much as good as what it’s allowed to examine itself in opposition to. The generator writes code, but it surely by no means will get to determine by itself whether or not that code is correct; pytest decides that. The boldness gate doesn’t ask the mannequin how positive it feels; it checks whether or not two unbiased makes an attempt land on the identical reply. And when neither of these checks clears, the system doesn’t retry endlessly, hoping the subsequent try is healthier; it stops on a hard and fast price range and fingers the issue to an individual with the total historical past connected.
When you take this additional, the pure subsequent step is course of reward fashions, which rating intermediate reasoning steps as a substitute of solely the ultimate go or fail — helpful as soon as your duties get complicated sufficient {that a} single end-to-end check can’t catch every part going improper alongside the best way. However for the massive majority of brokers value constructing, the sample on this article — floor the critic, cap the loop, log the failure — is the sturdy model of self-correction. It’s the one which survives contact with an actual manufacturing system as a substitute of only a clear demo.

